Yes, pseudonymised data remains personal data under the GDPR, because re-identification stays possible with separately held information (Article 4(5) and Recital 26). Removing names can materially reduce exposure without taking the working dataset outside data-protection law. The difficult question isn't whether a document contains visible names. It's whether the organisation can demonstrate that its transformation, access controls and intended use reduce identification risk sufficiently for the processing it proposes. A convincing pseudonymisation strategy therefore needs more than a masking tool: it needs evidence of separation, proportionate safeguards and a documented legal assessment. For decision-makers approving AI document workflows, the defensible position is to treat pseudonymisation as a governed process, not a compliance exemption.
What Does GDPR Mean by Pseudonymisation?
Pseudonymisation means transforming personal data so that attributing it to a specific person requires additional information kept separately under safeguards. The EDPB's pseudonymisation guidelines explain this definition under Article 4(5), an expressly defined concept in the GDPR when the regulation became applicable on 25 May 2018.
The definition concerns how an organisation processes and protects data, not merely what the resulting document looks like. A file containing coded names can still fail the practical purpose of pseudonymisation if its recipient can readily obtain the corresponding identities.
The conditions behind the definition
A defensible implementation addresses these connected requirements:
- Transform the data. Replace or modify identifying values so the working material doesn't directly attribute the information to the person.
- Separate the attribution information. Keep the mapping table, recovery key or equivalent information apart from the transformed dataset.
- Protect the route back to identity. Use technical and organisational controls against unauthorised attribution, including restrictions on who can recover the original values.
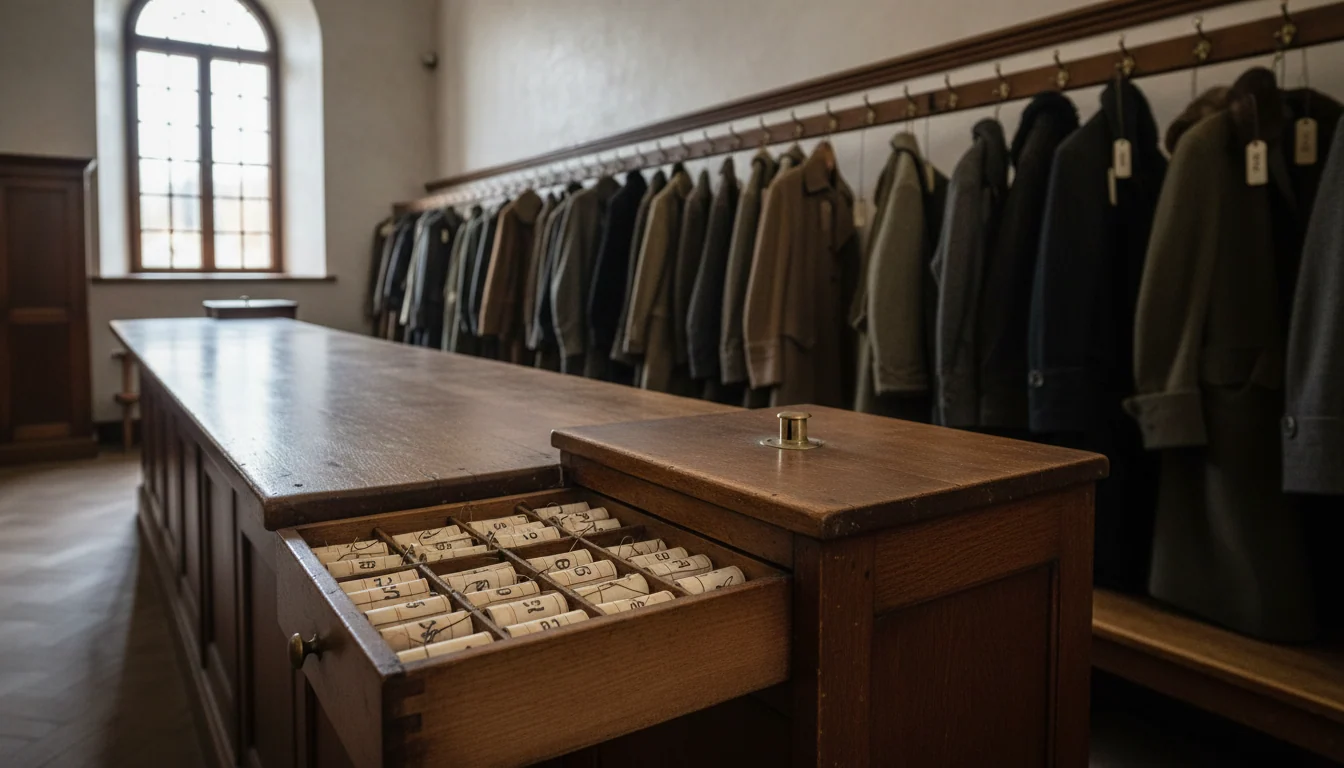
Consider a coat check. A numbered ticket attached to a coat doesn't identify its owner by itself, but the matching stub allows the cloakroom to connect the coat with the person collecting it. The useful analogy isn't that names become numbers. It's that the linking mechanism needs its own protection.
The analogy also has a limit: documents can disclose identity through their content even when their labels have changed. A distinctive account of an incident may identify someone without any lookup table.
Professional document handling therefore involves protecting both the text and the information that reconnects it to a person.
A safeguard, not a separate legal category
Pseudonymisation describes a protective process. It doesn't create an intermediate category of information that organisations can process without the ordinary discipline of data protection.
Project approval test: Identify where the attribution information is held, who can reach it and what prevents the recipient of the working data from obtaining it.
If those questions have no clear answers, the organisation has demonstrated substitution, not necessarily effective separation. That distinction determines how much confidence decision-makers should place in the safeguard.
Is Pseudonymised Data Still Personal Data Under GDPR?
Yes, a working dataset remains personal data where separately held information allows the organisation to reconnect it to individuals. The UK ICO's guidance on research safeguards explains that pseudonymised data doesn't identify someone from the dataset alone, but identification remains possible by referring to additional information.
That is UK regulatory guidance, not a substitute for an EU legal assessment. It nevertheless illustrates the operational distinction clearly: removing direct identifiers and removing reasonable identification possibilities are different outcomes.
Pseudonymised and anonymised data under GDPR
- Status under the GDPR — Pseudonymised data: Remains personal data; Anonymised data: Outside the GDPR where identification is no longer reasonably likely
- Re-identification material — Pseudonymised data: Held separately, such as a key, mapping table or vault; Anonymised data: No additional information allowing identification is retained
- Reversible — Pseudonymised data: Yes, with the separately held information; Anonymised data: Not intended
- Typical use — Pseudonymised data: Working data under security safeguards; Anonymised data: Statistics, research outputs and released datasets, subject to an effective identification-risk assessment
- Consequence for obligations — Pseudonymised data: GDPR duties generally apply, with reduced risk; Anonymised data: Duties generally fall away where identification risk is sufficiently remote
The table describes intended operating models, not automatic classifications. A research output doesn't become anonymous because it is published as a statistical report, and a released dataset doesn't become anonymous because its publisher deleted a name column.
Reversibility is an important warning sign, but it isn't the whole identification test. Destroying a lookup table doesn't establish anonymity if someone can infer identity from the remaining attributes.
Assess realistic identification routes
A sound assessment considers the effort needed to identify someone, the information available to the relevant parties and the technology they could reasonably use. Cost, time and technological developments matter because an identification route that is impractical in one context may be realistic in another.
Consider a hypothetical occupational-health dataset. Replacing employee names with codes preserves the organisation's ability to reconnect records through its personnel mapping. Deleting that mapping wouldn't settle the question if a distinctive role and incident description still identified an employee.
The ICO recommends applying these protective techniques at the earliest opportunity, ideally before research use. Operationally, that means deciding the intended identification boundary before distributing working copies, rather than trying to recover control after circulation.
If the team can reverse the output using a file it holds, plan for personal-data obligations. If it can't, assess other identification routes before calling the output anonymous.
Which Technical Methods Count as Pseudonymisation?
The strength of a method depends on the attacker model, the linkage the analysis requires and the protection of the secret. The replacement format alone says little. ENISA's guidance on pseudonymisation techniques and best practices identifies brute-force, dictionary-search and guesswork attacks, alongside techniques including random values, keyed hashing, tokenisation and encryption.
Common pseudonymisation methods and their trade-offs
- Random substitution with a lookup table — How it works: Replaces each identifier with a random value recorded separately; Linkability across records: None across documents when tokens are generated independently per document; Main risk to manage: The table becomes the re-identification key and needs separate protection
- Deterministic tokens using a keyed hash or MAC — How it works: The same input and secret produce the same token; Linkability across records: Yes, within the defined scope; Main risk to manage: Correlation between records and compromise of the secret
- Vault-based tokenisation — How it works: A vault issues tokens and maintains their relationship to original values; Linkability across records: Stable or document-specific, according to issuance policy; Main risk to manage: Vault permissions and access logging
- Encryption of identifiers — How it works: Encrypts identifiers under a separately held key; Linkability across records: Yes with deterministic encryption; randomised encryption needn't preserve equality; Main risk to manage: Key compromise exposes recoverable identifiers
- Generalisation of quasi-identifiers — How it works: Reduces precision, such as replacing exact ages with age bands; Linkability across records: Not a linking method; Main risk to manage: Rare combinations can remain identifying
Generalisation plays a complementary role. On its own it typically reduces the precision of revealing attributes that identifier substitution leaves untouched, so it works best alongside a substitution method rather than as a substitute for one.
Random substitution is useful when a document needs internally consistent references but no connection to other documents. Deterministic tokens support continuity across a defined analysis, while also revealing that matching records concern the same person. That trade-off is the central design choice: every unit of linkage you retain is a unit of correlation an attacker can also use.
Choose the minimum necessary linkage
Plain hashes of predictable names are a weak design choice because an attacker can test likely inputs. Keyed methods introduce a protected secret, but that secret then becomes a critical security asset in its own right.
ENISA's technical guidance addresses the underlying architectural risk: the secret and the dataset shouldn't be handled in the same file, and stored secrets need encryption and proper key management. A defensible implementation goes further and produces evidence. Restrict recovery permissions to named roles, log each key access and remove insecure temporary copies. Those records are what turn pseudonymisation from a claim into a governed process an auditor can verify.
For an analytics project, define the legitimate linking scope before choosing tokens. Teams weighing connections across systems can draw planning context from PlotStudio AI's cross-platform analytics guide; the privacy decision remains whether those connections are necessary for the approved purpose, and that balancing test should be documented rather than assumed.
Where continuity isn't needed, document-randomised tokens are a more restrained default. No identifier technique prevents inference from a rare combination of remaining attributes, which is why method selection, secret handling and linkage scope all belong in the same written record.
What Legal Duties Still Apply to Pseudonymised Data?
Pseudonymised records remain personal data, so the core GDPR duties continue to apply in full. Article 25 of the GDPR names pseudonymisation as an example of a protective measure and requires safeguards proportionate to the processing context and risks. It provides no safe harbour: the organisation still has to explain why it processes the data, how it protects people and who is accountable.
A lower-risk representation of a record does not replace that explanation.
Duties translated into operating decisions
- Lawful processing. Establish an appropriate lawful basis for each purpose. A protective transformation does not itself justify collecting or using information.
- Privacy by design and default. Decide which information is necessary, which people need access and what the default configuration permits.
- Appropriate security. Protect the working dataset and the attribution information through suitable separation, permissions and recovery controls.
- Individual rights. Maintain workable procedures for access, rectification, erasure, restriction, portability and objection, where applicable, and honour withdrawal of consent where processing relies on it.
These rights carry conditions and exceptions; they do not apply identically to every processing activity. Objection to processing based on legitimate interests requires its own balancing assessment rather than treatment as an unconditional deletion instruction. Documenting that assessment is part of the duty, because Article 25's proportionality test weighs the state of the art, implementation costs, the nature, scope, context and purposes of processing, and the risks to individuals. It prescribes no universal token format or fixed technical threshold. Our discussion of privacy by design as a lifecycle engineering duty develops the operational consequence: safeguards need maintenance as processing changes.
Assign responsibility to people and records
Where a customer uses our service to process professional documents, the customer is generally the controller and The Coding Company B.V. the processor, as defined in the applicable agreement. Those contractual roles should match the actual processing arrangements, and an access or erasure request can concern both the working record and the associated attribution data. Write retention and deletion rules for the mapping alongside those for the dataset, account for applicable exceptions and preservation duties, and keep evidence showing why the chosen safeguards were considered proportionate at the time.
Governance consequence: A pseudonymised file needs an accountable owner, a retention decision and a rights-handling route, not merely a technical label.
Keep jurisdictions distinct. The EU GDPR framework applies in the EU; UK GDPR obligations and ICO guidance apply in the UK, with their own legal context and enforcement.
How Does Local Pseudonymisation Work for AI Documents?
Local pseudonymisation replaces identifying values before approved document context reaches an external model, while retaining controlled recovery information separately. Consider a law firm seeking an AI summary of a witness statement containing the client's name, date of birth and case number.
The following visual illustrates the separation between source material, transformed input and authorised restoration. The appropriate legal description of the transmitted working text is pseudonymised, not a claim that identification is impossible.
A defensible document-handling sequence
- Identify relevant identifiers. Include names, dates of birth and case references, together with identifying passages in free text. A field list alone can miss a witness's name repeated inside the narrative.
- Detect values locally before external calls. Apply the check to the actual material being submitted, including revised drafts and selections. Testing an earlier version doesn't establish what leaves during a later request.
- Replace values consistently within the document. Preserve party roles so the model can distinguish the client, witness and opposing party. Inconsistent placeholders can cause the summary to merge people or misattribute statements.
- Keep the mapping separately restricted. Store recovery information outside the submitted context, with access limited to authorised functions. Attaching the lookup table to the same request defeats the intended separation.
- Check the outbound context and stop failed requests. Inspect what will be transmitted, rather than relying on an earlier successful test. Treat each submission as a new release decision.
- Send only the necessary transformed context. Exclude irrelevant attachments and surrounding case material. Our data-minimisation workflow for generative AI addresses that selection decision.
- Review the output before local restoration. Check attribution, omissions and unsupported statements before reconnecting identities. Restoration shouldn't turn an unreviewed summary into a final professional record.
Separate privacy controls from drafting quality
A resource such as LegesGPT's AI legal document generator is relevant when considering AI-assisted drafting workflows, but the decision to use any external service remains separate from approval to disclose case material.
If the check fails, no document text is sent to an external model. This is a pseudonymisation layer that reduces risk without removing the resulting personal data from regulatory scope; its documented behaviour should be assessed against the intended use.
The accompanying video provides additional workflow context.
Before approval, record where the mapping is stored, who can access it and how a failed outbound check is handled. Those are testable control questions, not assurances about the accuracy of the resulting legal analysis.
Which Residual Risks and Evidence Should You Require Before Relying on Pseudonymisation?
Approve the workflow only after documenting residual identification risk, the legal basis for use and evidence that its controls work. Customers' questions and shielded text go to the AI models they choose, and those providers may process data outside the EU. Where Chapter V GDPR applies, provider and customer arrangements need an appropriate transfer mechanism, such as an adequacy decision or Standard Contractual Clauses.
Our privacy controls don't detect every indirect identifier and don't make re-identification impossible. A job title, a town and an exact date can point to a person without including their name.
In our analysis, the controller should explicitly evaluate and accept remaining risk rather than leave that judgement to the tool. The relevant question is whether the proposed safeguards are adequate for this recipient, this dataset and this purpose.
A balancing test is not a security checklist
The EDPB's announcement of its January 2025 pseudonymisation guidance explains that pseudonymisation may make reliance on legitimate interests under Article 6(1)(f) easier and assist compatibility assessments under Article 6(4), while other GDPR requirements continue to apply.
That is not a finding that every pseudonymised use is lawful. Nor does it mean every project needs a legitimate-interests balancing test regardless of its legal basis.
Where legitimate interests is the proposed basis, document the interest pursued, why the processing is necessary, and how the organisation balances that interest against individuals' rights and interests. If the organisation proposes a new purpose, assess that purpose separately rather than assuming that improved security makes it compatible.
A security control can improve a legal assessment without supplying its conclusion.
Evidence to take to the approval meeting
Use an evidence register that connects each control with an owner, a test and an approval decision:
- Identifier map. Record direct identifiers, quasi-identifiers and revealing free-text passages. Show which are substituted, generalised, excluded or deliberately retained, with reasons.
- Attribution-data ownership. Identify who holds the mapping and who can recover identities. Retain evidence of permissions, access logs and the handling of exceptional access.
- Purpose and legal assessment. Document the intended use, necessity and appropriate lawful basis. Include a balancing test when relying on legitimate interests, and a compatibility assessment where relevant to secondary use.
- Retention rules. Set out how long source files, transformed inputs, outputs and mappings are kept. Explain how deletion works across these related records rather than treating the vault as an unrelated system.
- Processor and transfer arrangements. Identify recipients and subprocessors, relevant processing locations and the applicable contractual arrangements. Confirm the transfer mechanism where international-transfer rules are engaged.
- Re-identification testing. Test realistic attempts using plausible auxiliary information. Include rare combinations, repeated references and cross-document correlation, not just whether the obvious name disappeared.
- Failed outbound-check records. Retain enough evidence to demonstrate that unsuccessful checks stopped transmission. Design those logs so they don't become an unnecessary duplicate store of sensitive document text.
- Review triggers. Reassess when datasets, recipients, model providers, linking requirements or threats change. Assign someone responsibility for recognising those changes and reopening approval.
The distinction between isolation, linking and inference helps organise these tests. Our analysis of identification risks in AI workflows explains why removing obvious identifiers doesn't settle each risk.
More articles on this subject are collected in the AI privacy and GDPR overview.
Sources and references
- EDPB's pseudonymisation guidelines
- UK ICO's guidance on research safeguards
- Pseudonymisation techniques and best practices
- Article 25 of the GDPR
- EDPB adopts pseudonymisation guidelines and paves the way to improve cooperation with competition authorities | European Data Protection Board
- Cross Platform Analytics: How Researchers Join Data Safely
- AI Legal Document Generator | Any Legal Doc in Minutes
Sources: Core legal claims are attributed to the EDPB's pseudonymisation guidelines on Article 4(5) and the UK ICO's research safeguards guidance; technical method context draws on ENISA's pseudonymisation techniques and GDPR Article 25.